Articles
Technical Leadership: A Task Has an Assignee. The Commitment Belongs to the Team.
 Ammar Najjar · October 31, 2026 · 4 min read
TL;DR When time-sensitive work stops moving, someone other than the unavailable assignee must explicitly own the decision about what happens next.
I recently saw two pieces of work sit untouched for almost two weeks even though both had clear deadlines.
Read more →Making AI Memory Capture More Reliable
 Ammar Najjar · October 26, 2026 · 5 min read
TL;DR Tool-specific integrations capture supported conversation events and place them in a shared queue. A separate workflow reviews the captured information and adds useful context to persistent memory.
In Building a Local AI Memory Repository, I established a Markdown repository as a persistent, agent-accessible knowledge source. Agents could read from it and update it, and it gave me a stable place to store what mattered across sessions. The approach worked, but memory maintenance still depended on agents remembering to perform additional steps during ordinary conversations.
Read more →Technical Leadership: Treat Late Constraints as a Test of the Decision
 Ammar Najjar · October 24, 2026 · 4 min read
TL;DR Check a late constraint against the reasons for the preferred option. Revisit the affected criteria and keep the rest of the reasoning available.
I was recently involved in a planning decision with two reasonable options. We had compared practical constraints, looked at who could participate, weighed cost and logistics, and gradually developed a preference. The choice was not final, but the discussion had enough momentum that it started to feel settled.
Read more →Building a Local AI Memory Repository
 Ammar Najjar · October 21, 2026 · 9 min read
TL;DR A local Markdown repository keeps AI memory on your machine, so you don't have to copy context between tools by hand, and you keep control over what each tool can see.
In When AI Memory Doesn't Follow You Between Tools, I described how I used Obsidian to share knowledge between ChatGPT, Claude Code, and local AI models. That approach worked, but retrieving relevant information and preserving new observations still depended on me initiating each step.
Read more →Technical Leadership: An Invitation Only Creates Ownership When Declining Is a Real Option
 Ammar Najjar · October 19, 2026 · 4 min read
TL;DR A leader's invitation carries weight that can turn an opportunity into compliance. Say plainly whether it is required or optional, then let a decline stand.
By the time this happened I had started opening some of our recurring technical discussions to people who would otherwise only receive the outcome. The reason is the one I wrote about in Ownership Starts Before the Decision: I wanted colleagues to build that context directly rather than always receiving it through me.
Read more →When AI Memory Doesn't Follow You Between Tools
 Ammar Najjar · October 16, 2026 · 8 min read
TL;DR AI memory helped me build on past conversations, but knowledge stayed split across tools. Using Obsidian as a shared source showed what's possible, while revealing where manual context transfer still needs work.
I use several AI tools regularly, each for a different purpose. ChatGPT helps with developing ideas, writing articles, reviewing texts, and reflecting on experiences. Claude Code supports my technical work, from investigating problems to planning implementations and reviewing architectural decisions. Local AI models handle personal material I prefer to process on my own machine.
Read more →Technical Leadership: Ownership Starts Before the Decision
 Ammar Najjar · October 14, 2026 · 4 min read
TL;DR Invite colleagues who may face similar decisions to see the reasoning while it develops. Keep summaries available and treat greater independence as an aim to work toward.
For a while, I treated information flow mainly as a communication problem. When something important happened in an architecture, operations, or cross-team discussion, I tried to make sure the relevant people heard about it afterward. I summarized decisions, shared links, and added notes where they could be found later. That helped with transparency, but I started to notice a limitation in this approach.
Read more →Keeping Knowledge Useful: What I Learned from 1,000+ Obsidian Notes
 Ammar Najjar · October 11, 2026 · 8 min read
TL;DR My move from Notion to Obsidian gave me a file-based foundation. Reviewing more than 1,000 notes showed me how tags, metadata, links, and navigation need to evolve with the collection.
I recently took a closer look at my Obsidian vault, a collection that has grown steadily over time. It contained more than 1,000 notes and supporting Markdown files on books, conversations, technical knowledge, decisions, and writing. Among them, I found tags with overlapping meanings, book notes with incomplete metadata, several decisions stored together in a long file, and navigation pages containing little more than a heading.
Read more →Technical Leadership: A Good Impact Story Still Needs a Measurable Direction
 Ammar Najjar · October 9, 2026 · 3 min read
TL;DR Separate local value from expected movement. Ask what should change in the outcome you care about, and proceed with open eyes when the answer is learning or risk reduction.
Before one planning discussion, I noticed that part of the data we needed was missing. We already had a broader business goal, but the dashboard did not make it easy to see how much our own product was contributing to it. Before the discussion, I worked with a colleague to add a per-channel breakdown that made our product's share visible. Once that view existed, we could look at the current state directly and ask how each planned initiative was expected to move it.
Read more →Technical Leadership: Turn Disagreement into a Testable Decision
 Ammar Najjar · October 1, 2026 · 5 min read
TL;DR Replace longer debate with a small spike: agree on the criteria first, review the evidence together, then decide.
I recently found myself in an engineering discussion that kept circling around the same disagreement. We were considering two ways of structuring part of a frontend application, and both had reasonable arguments behind them. One approach promised a cleaner separation and more consistent structure. The concern from the other side was that we would pay for that structure with additional indirection and make future changes harder to follow.
Read more →Technical Leadership: Separate the Practice from the Problem
 Ammar Najjar · September 28, 2026 · 3 min read
TL;DR Name the problem, the outcome, and the constraints first. Then the proposed practice becomes one option among several, and the team can keep the problem even if it rejects the solution.
In one team conversation, we were discussing whether to introduce test-driven development. The discussion could easily have turned into the usual exchange of opinions about TDD, its benefits, its overhead, and whether it fits the way the team works.
Read more →Technical Leadership: Stop Acting as the Proxy
 Ammar Najjar · September 24, 2026 · 4 min read
TL;DR Help clarify the problem, then step out: connect the decision-maker with the affected person instead of carrying the decision back and forth.
A situation I have encountered is this: someone brings me a request that needs an exception, and that exception can only be granted by whoever owns the decision. My first impulse used to be to carry it forward myself: explain the context, bring the answer back, and handle the follow-up questions in between. What has worked better is helping sharpen the request and then connecting the person directly with them, so the reasoning behind the answer arrives firsthand instead of through my retelling.
Read more →My Local AI Setup, Six Months Later: 48 GB, Qwen3.8, and a Different Bottleneck
 Ammar Najjar · September 22, 2026 · 9 min read
TL;DR Six months after the 16 GB setup: 48 GB, one default 27B model, Splash inference in LM Studio, and 64K context, because the constraint moved from fitting a model to keeping long agent sessions usable.
A few months ago, I wrote about running a useful local AI development setup on a MacBook Pro with 16 GB of unified memory. At the time, memory shaped almost every decision. I experimented with smaller models, limited context carefully, and looked for a combination that was capable enough for coding while still leaving room for my IDE, containers, browser, and the rest of my development environment.
Read more →Technical Leadership: Give Autonomy a Time Boundary
 Ammar Najjar · September 17, 2026 · 3 min read
TL;DR Autonomy works when the team owns the approach and the leader makes the outcome, the fixed constraints, and the review point explicit.
In a discussion about an operational problem, the team had several reasonable ways to handle it. I had a preferred approach, but the group wanted to try something different. My first instinct was to keep the discussion open and let them work through it. I wanted to give them room to decide, but an important question remained unanswered: when would we know whether their approach was working well enough?
Read more →My Local AI Coding Toolkit: How I Keep Agents Fast and Token-Efficient
 Ammar Najjar · August 23, 2026 · 15 min read
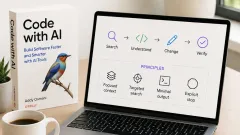
TL;DR How I optimize the environment around AI coding agents to reduce token waste and keep sessions efficient.
AI coding agents have become part of my daily workflow. I use OpenCode and Claude Code for everything from exploring unfamiliar codebases and investigating bugs to implementing changes, reviewing code, and working through architectural questions.
Read more →ngrx-graph: Static Analysis and Graph Visualization for NgRx Applications
 Ammar Najjar · July 31, 2026 · 13 min read
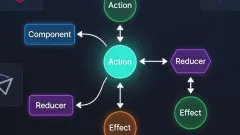
TL;DR ngrx-graph scans NgRx codebases via AST parsing, resolves aliases and nested actions, and outputs focused or project-wide action flow graphs in DOT/SVG. One command replaces hours of manual code tracing.
If you have ever traced an action through a sprawling NgRx codebase, wondering which effect listens to it, which reducer handles it, and whether some other effect silently dispatches another action in the chain, you know the pain. Manual code traversal works until it does not. One missed dispatch() call buried in a mergeMap. Your mental model breaks.
Read more →How I Configure Cloudflare for My Website
 Ammar Najjar · July 22, 2026 · 11 min read
TL;DR A systematic review of every Cloudflare Free plan setting, what stays on, what gets disabled, and the principles behind each decision.
Open your Cloudflare dashboard today and you'll find dozens of features for improving performance, security, and reliability. Some are enabled by default, others are recommended, and new capabilities appear regularly as the platform evolves. With so many options available, I wanted to better understand how each setting contributed to my website.
Read more →How This Website Works: A Technical Look at the Stack
 Ammar Najjar · July 19, 2026 · 15 min read
TL;DR A complete technical breakdown of how this site is built, from Bun + Astro content pipeline to Cloudflare deployment, minimal JavaScript, and performance optimizations.
In a companion article, I wrote about why I rebuilt this website with Astro and how that decision grew into a much larger project. That article was about the journey and the thinking. This one is about the outcome: how the website actually works, every layer from writing a post to it appearing in a reader's browser.
Read more →A Lunch Conversation Changed My Website
 Ammar Najjar · July 19, 2026 · 13 min read
TL;DR How a casual lunch discussion led to rebuilding this site with Astro, modernizing the entire stack, and rethinking it as a personal digital workshop rather than a traditional portfolio.
Some of the most enjoyable projects I've worked on have started in surprisingly ordinary moments. A conversation introduces a new idea, someone shares an experience from their own work, or I come across a different way of approaching a familiar problem. The conversation eventually ends, everyone returns to their daily work, yet one small idea continues to occupy my thoughts. Over the following days that idea slowly grows into documentation, notes, experiments and, occasionally, an entirely new project. Looking back, I can trace many of my favorite learning experiences to moments exactly like these, and rebuilding my personal website became another one of those unexpected journeys.
Read more →Making Angular AI Work in Real Projects
 Ammar Najjar · July 13, 2026 · 6 min read
TL;DR AI tools are great at generating code, but real Angular projects succeed only when you give them rich project context, architecture boundaries, and conventions.
AI can generate a component, write a test, or explain a compiler error. But in real applications, results depend more on project context than model capability. It doesn't understand your architecture, your conventions, or the boundaries you built over years.
Read more →Every Camera Tells a Story
 Ammar Najjar · July 8, 2026 · 7 min read
TL;DR A personal reflection on how cameras shape our photography, creativity, and the stories we choose to tell through images.
Every now and then, I catch myself looking at new cameras. I open another review, compare another specification sheet, or watch yet another photographer explaining why this year's camera is better than last year's. It always begins with a simple curiosity, and before I realize it, hours have passed. Somewhere between comparison videos, photography forums, and used listings, I find myself imagining what it would be like to own a different camera.
Read more →Nine Years on GitHub Pages, Why I Finally Moved to Cloudflare
 Ammar Najjar · July 3, 2026 · 9 min read
TL;DR Why I migrated this site from GitHub Pages to Cloudflare after nearly a decade, including the migration process, challenges, and discovered trade-offs.
For nearly nine years, my personal website lived on GitHub Pages. It was free, reliable, and required almost no maintenance, so why migrate? A recent move to Cloudflare Pages prompted this post, which covers the motivation behind the change, the migration process, the issues encountered, and the trade-offs discovered along the way.
Read more →Local AI on a MacBook Pro with 16 GB RAM: What Actually Works
Ammar Najjar · June 14, 2026 · 9 min readTL;DR Practical guide to running local AI coding assistants on a 16GB M1 MacBook Pro, what works well, what doesn't, and the real setup trade-offs.
Running AI coding assistants locally sounds appealing: no API costs, your code stays on your machine, and you get a Claude Code-like experience for free. But getting it to actually work well on a 16 GB MacBook Pro M1 takes more trial and error than most guides admit.
Read more →Essential Development Tools: My Brewfile Setup
Ammar Najjar · February 23, 2026 · 9 min readTL;DR My curated list of essential macOS development tools via Homebrew that significantly boost daily productivity and workflow enjoyment.
As a software engineer, our toolset shapes how we work and what we can accomplish. Over time, I've curated a collection of essential tools that boost my productivity and make development more enjoyable. Here's a breakdown of my Homebrew setup, featuring the tools I use daily.
Read more →Portfolio: a lightweight personal portfolio tracker
Ammar Najjar · December 12, 2025 · 6 min readTL;DR This post explains the design and implementation of a simple browser based personal portfolio tracker built with React, TypeScript, and Vite, covering requirements, challenges, and solutions for state handling, caching, and charts.
This post explains the design and implementation of a small browser-first portfolio tracker. It focuses on requirements, the challenges encountered, and how the final solution addresses them, including code snippets that illustrate the state handling, caching, and chart interaction.
Read more →Mastering Git Commands: A Practical Guide
Ammar Najjar · July 8, 2025 · 13 min readTL;DR A practical selection of essential Git commands that help developers track changes more effectively, collaborate smoothly, and manage project history with confidence.
Git is an indispensable tool for version control, enabling developers to track changes, collaborate effectively, and manage project history. While its capabilities are vast, a solid understanding of key commands can significantly streamline your workflow. This article delves into a selection of practical Git commands, explaining what they do, how to use them, and when they are most effective.
Read more →Angular - Content Projection
Ammar Najjar · June 20, 2021 · 4 min readTL;DR Content projection in Angular enables flexible and reusable components by allowing you to insert content from parent components into child components.
Content projection is a feature in angular that supports inserting a component in another component. This changes the way an angular developer designs his application/library by implementing flexible and reusable components, a boundary I revisit when making Angular AI work in real projects.
Read more →Reactjs: Arrays in jsx
Ammar Najjar · November 24, 2019 · 1 min readTL;DR Quick tip on using JavaScript array map to render dynamic lists of elements in JSX instead of hard coding repeated components for cleaner and more maintainable React code as shown in the Tic Tac Toe board example.
When I tried out Reactjs tutorial few months ago, I noticed that in the official starter code, they repeated same div elements in the render() method, just in case of change in the source, I will list it here:
Read more →Fetch using Gitlab API
Ammar Najjar · February 19, 2019 · 2 min readTL;DR Python script that uses the GitLab API with a private token to automatically clone or fetch all your accessible repositories handling configuration via JSON and providing both argparse and config file versions for convenience.
Between gitlab repos that need daily tracking and frequent machine changes, the manual cloning and sync process became exhausting. An automation script was the obvious next step to offload the boring tasks.
Read more →PyConDe & PyData 2019
Ammar Najjar · January 1, 2019 · 6 min readTL;DR Personal diary style recap of attending PyConDE and PyData 2019 in Berlin covering keynotes talks tutorials sprint days and personal highlights such as meeting core developers and contributing to Bokeh.
Fresh back from PyConDe & PyData-2019, this post shares and documents the experience. Think of it as a diary more than a blog, covering:
Read more →RxJS Series - Observables
Ammar Najjar · January 1, 2019 · 6 min readTL;DR Introduction to RxJS Observables covering the core concepts of Observer Subscriber and how to create them from scratch or using handy static methods like of range interval timer from fromEvent and create with practical code examples.
RxJS (on Github) is a reactive programming library for Javascript, and in this series, I would like to expose my way of learning it with you.
Read more →Custom Selenium Webdrivers using Decorators
Ammar Najjar · April 9, 2017 · 4 min readTL;DR Learn how to dynamically create custom Selenium WebDriver classes for different browser versions using Python decorators and class factories so you can easily run tests with multiple Firefox and Chrome binaries in parallel.
How to create custom selenium webdriver classes dynamically with a parametrized browser binary path?
Read more →Fedora23 Upgrade (unlabeled home)
Ammar Najjar · July 3, 2016 · 1 min readTL;DR Quick fix for the SELinux labeling issue that occurs after upgrading to Fedora 23 or 24 where the home directory becomes unlabeled preventing user login simply run sudo restorecon -R /home to restore correct permissions.
When I tried to update from the fedora23 to fedora24, I faced the issue that the home directoy lost its labeling:
Read more →Build Vim from Source
Ammar Najjar · June 23, 2016 · 1 min readTL;DR Step by step guide and bash script to build the latest Vim from source on Fedora with huge features enabled including Python3 Ruby Lua Perl support and GUI for full functionality.
Many times when I want to use vim which comes within the main repo of any Linux distro, I find that it is missing some kind of support, either python or client-server mode, or any other feature. And there for I have to build it manually from source and install it. I documented the resulting setup piece by piece in my vimrc adventure.
Read more →Lwa4p Robot Arm Setup
Ammar Najjar · June 22, 2016 · 5 min readTL;DR Step by step guide with a bash script for setting up the Schunk LWA4P robot arm on ROS Indigo using an ESD CAN card including CAN interface configuration MoveIt integration and troubleshooting tips to get the arm initialized and moving.
Experiments with the powerball lightweight lwa4p robot arm from Schunk came with many difficulties getting it to move using moveit. This post shares that experience.
Read more →Adventure through my vimrc (nvimrc)
Ammar Najjar · June 19, 2016 · 9 min readTL;DR A detailed walkthrough of useful configurations mappings and customizations in the authors vimrc init.vim file covering general settings plugins status line and productivity enhancing tricks for Vim and Neovim.
In this post I'm going to take you in an adventure in my previously vimrc and currently init.vim which I collected from using vim then neovim along the last few years. I will explain the feature or the function, then include the configurations or code that should be inserted in the vimrc (init.vim) file to activate that feature.
Read more →Opencv on Openshift
Ammar Najjar · June 17, 2016 · 1 min readTL;DR This post provides a bash script and step by step instructions to successfully install OpenCV in a Python 2.7 cartridge on OpenShift Online while working around the strict 1GB quota limitation.
When I wanted to intall opencv on my python-2.7 openshift online cartridge I faced the problem of quota limitation to 1GB.
Read more →